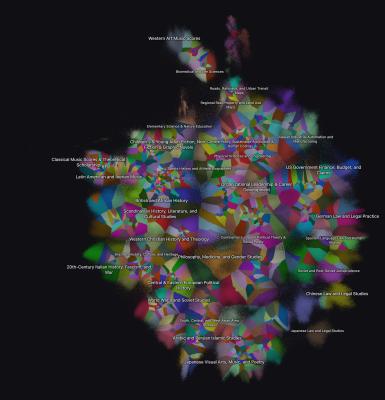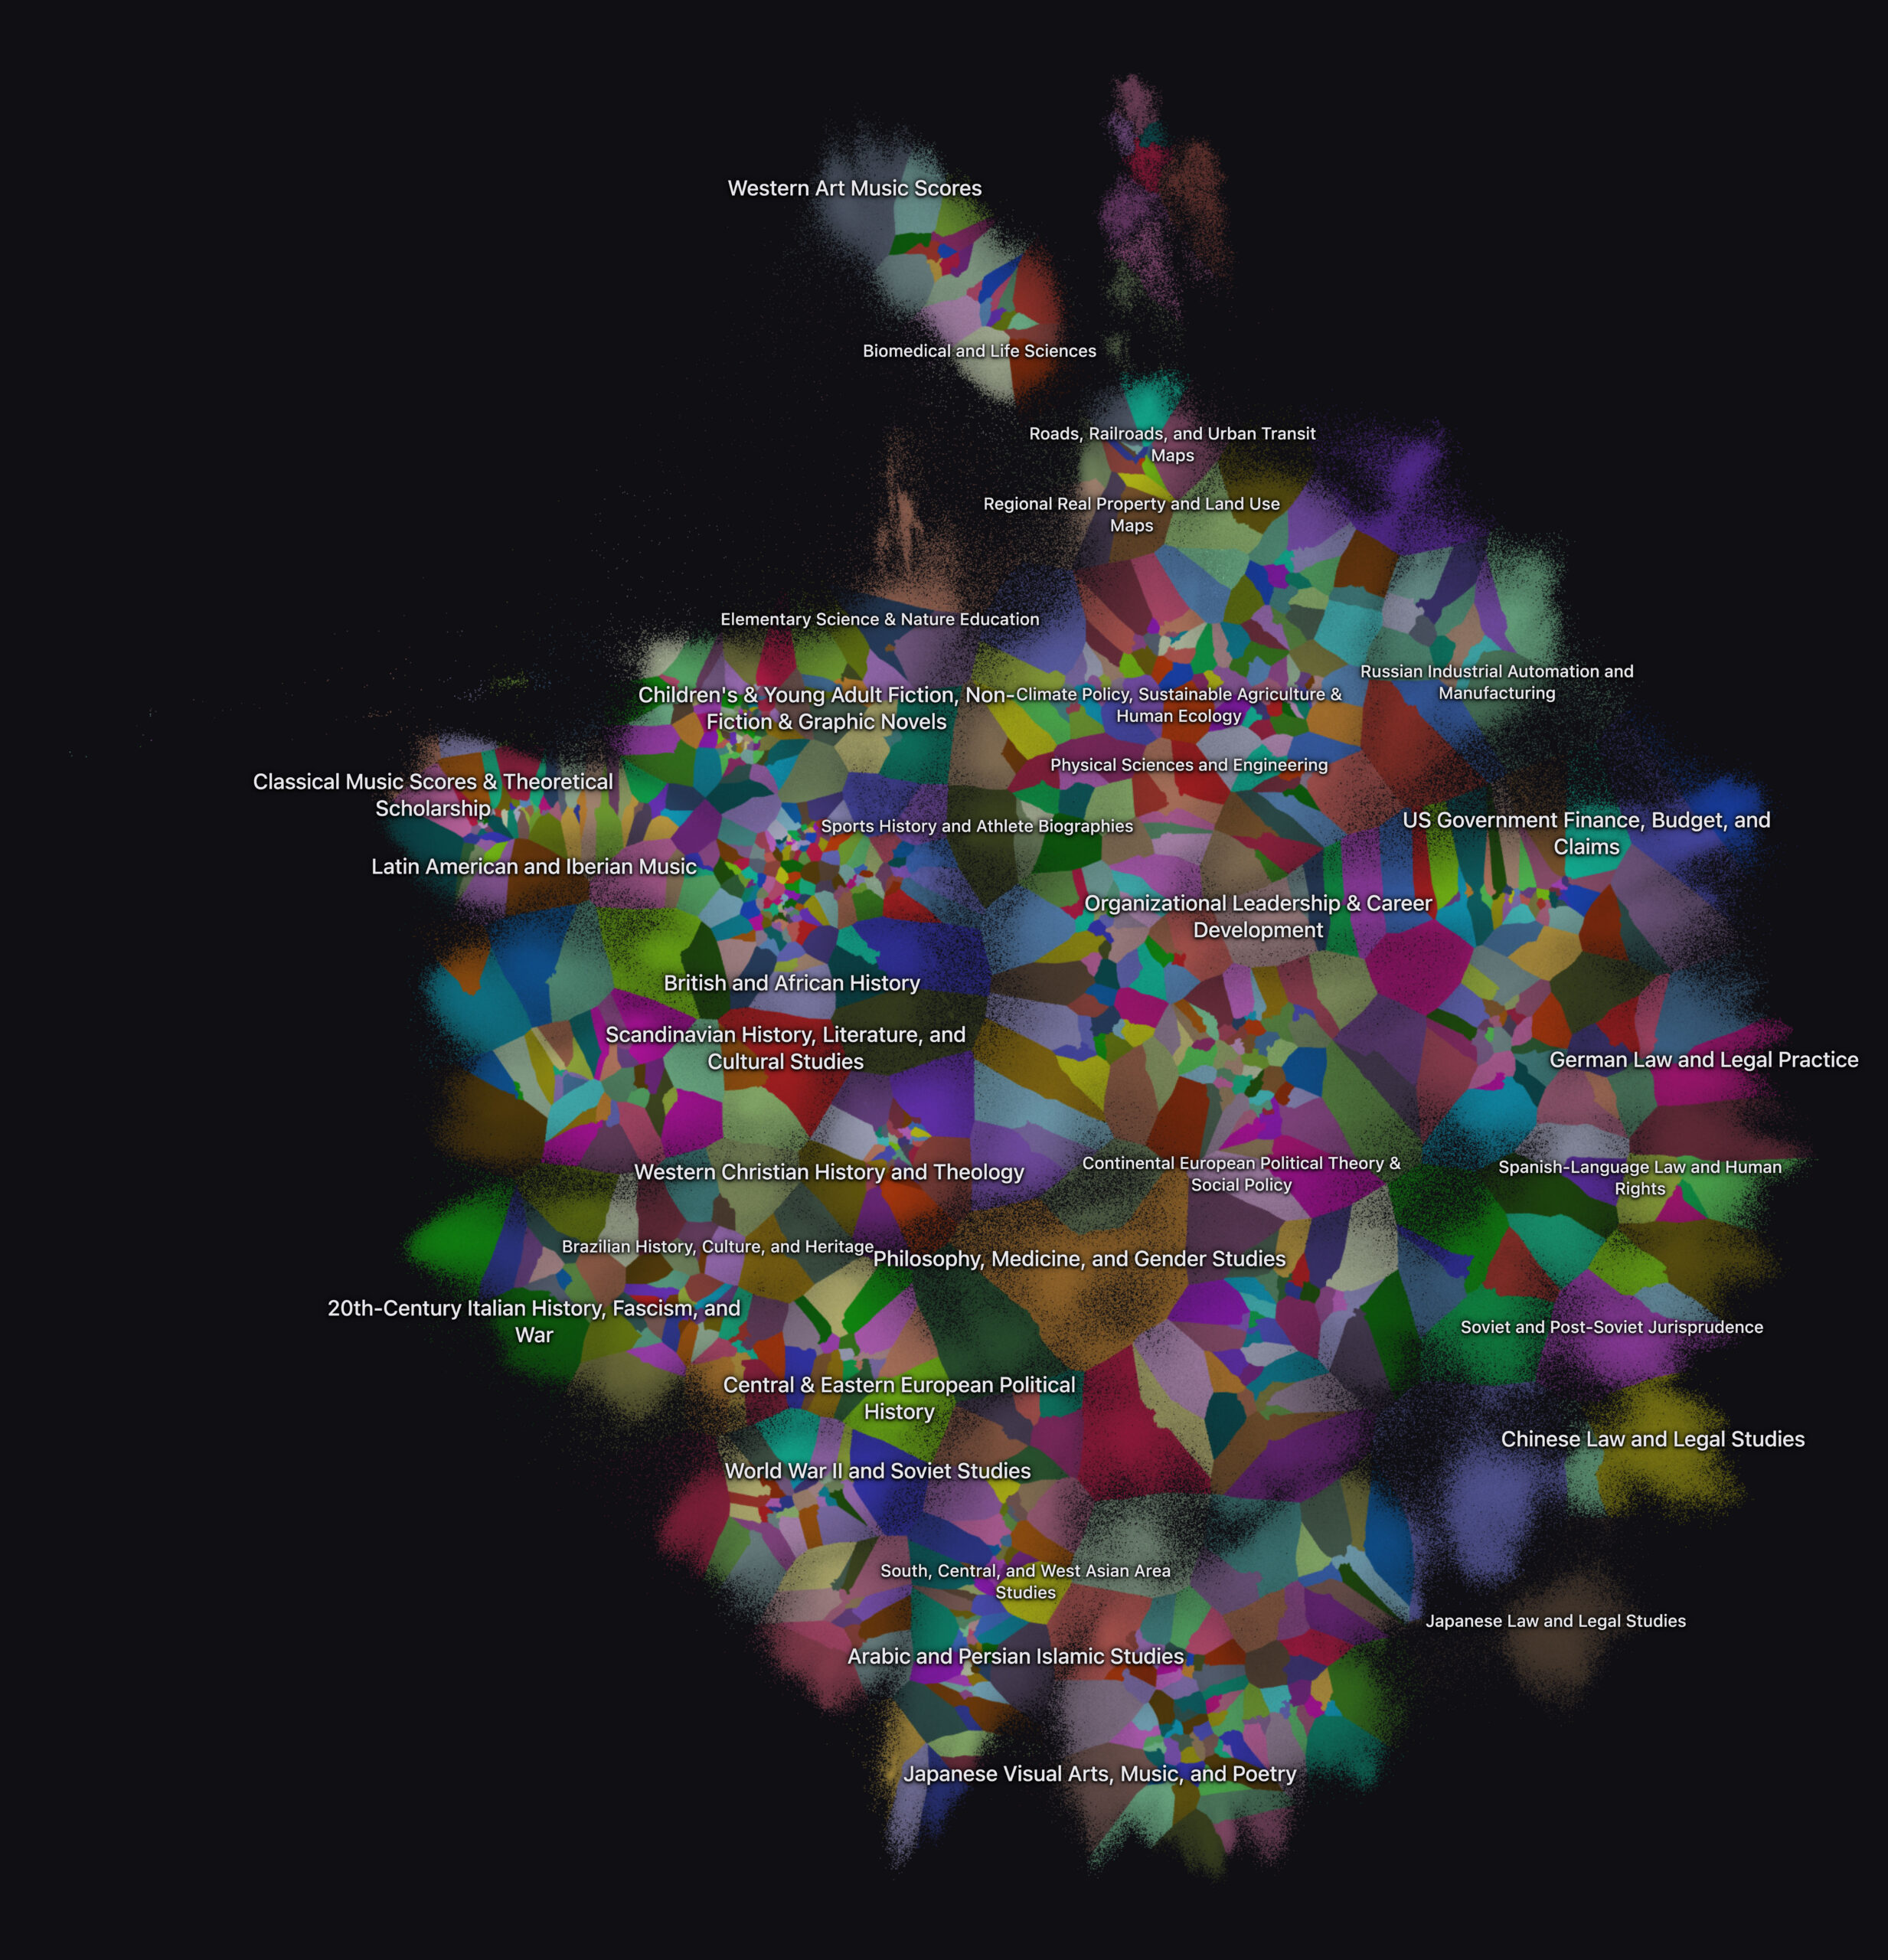
Matthew Miller writes about some experimentation with vector embeddings at the Library of Congress. "Vector embeddings, in the simplest terms, are numbers that represent text. They are used in many machine learning and AI tools and provide a way to reduce natural language to numbers, which enables us to interact with language using algorithms." What they did was to transform a user's query into a "phantom record" in order "to find where in the embedding model and our existing records it would be located." Visualizing the catalogue, the system "also has a 'Communities' toggle that provides a view of the catalog in line with the embedding model's internal organization." Here are all the embeddings files.
Today: Total: [] [Share]